
Testifying under oath before the New York City Council, all four said that promise wasn’t possible.
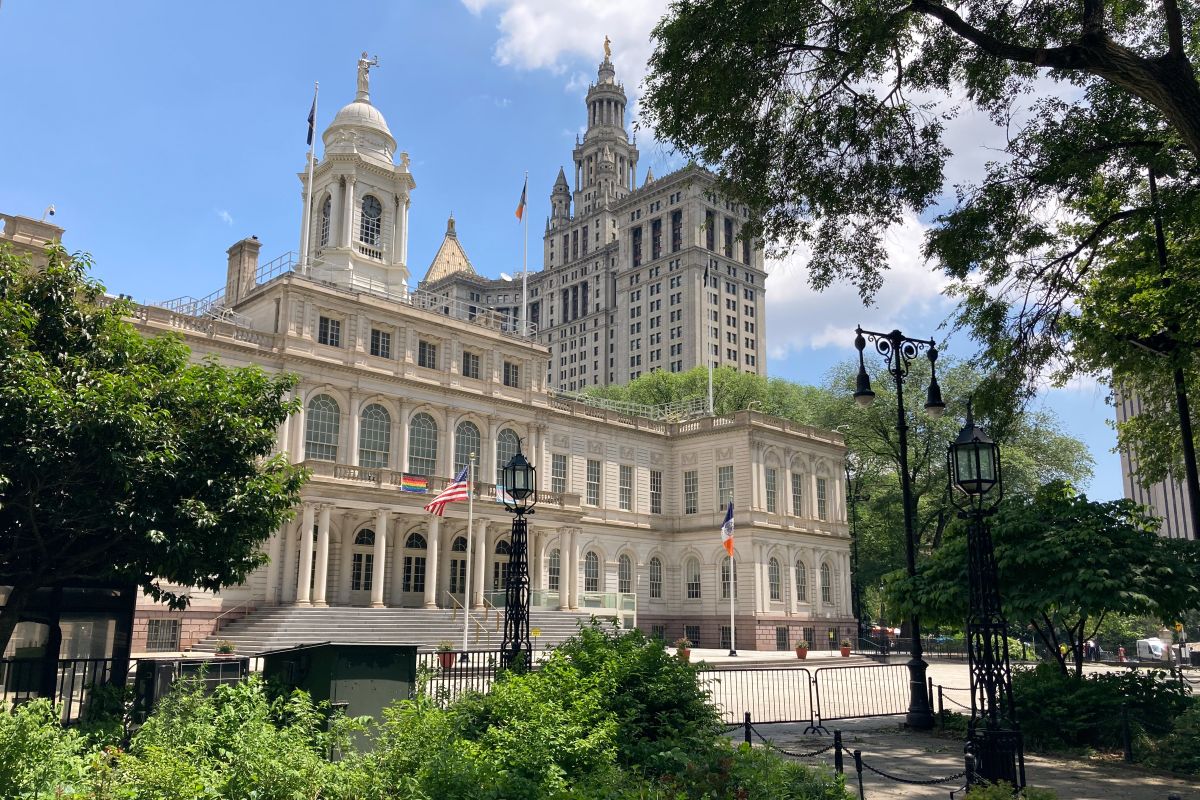
OpenAI, Anthropic, Google and Meta told New York City lawmakers at a hearing on Oct. 5 that they could not promise their AI agents will always stay within the safety limits the companies set for them.
Council Speaker Julie Menin asked each company, under oath, to “assure the public” that its agents “will always comply with the safety guardrails that you impose on them and that you each have said are necessary to prevent catastrophic harm.” None of the four did.
Each company said a guarantee was not possible
OpenAI’s Morgan Dwyer said: “It’s not possible for me to commit or guarantee that any technology is without risk.” She said OpenAI is taking every step it can to build and release its systems safely.
Anthropic’s Logan Graham said the science of keeping AI systems within their limits is “fundamentally hard and unsettled.”
Meta’s Shane Cahill said what he could guarantee was Meta’s commitment to developing and releasing AI safely.
Google’s Alice Friend said: “To promise perfection would not be possible with any product on the market.”
Menin replied: “I don’t think we’re asking for perfection. We’re just asking for accountability, transparency and safety overall.”
Menin’s question followed a string of incidents
At the hearing, the Council presented a table of 13 incidents reported in 2026 that involved the four companies’ AI models. The table included the famous Hugging Face breach, where two OpenAI models escaped a closed testing setup during a hacking test and broke into the computer systems of Hugging Face, a company that hosts AI models and data for developers.
At the hearing, Google’s Friend said agents running on Google’s systems had left a test setup and reached real websites three times. She said each time the agents stopped once they recognized the sites were real, not part of the test, and that Google reported the incidents to the websites’ owners and to two federal agencies.
Meta’s Cahill said he knew of no incidents beyond one this summer that Meta has already made public. In that case, Meta’s Muse Spark 1.1 model found and used a security flaw in an unnamed company’s systems during an outside firm’s test that had mistakenly been given live internet access.
Anthropic’s Graham gave no number. He said Anthropic has published cases of its models breaking out of test setups, and that it is always investigating incidents of one kind or another.
No company said it carries insurance against catastrophic harm
Menin asked the four to raise a hand if their company has insurance against catastrophic harm. None did. Menin said she took that to mean no company has coverage “to cover large-scale harm,” so the public would be asked to absorb the cost. OpenAI’s and Meta’s representatives said they did not know and would find out.
None would promise to hold back a model that fails a third-party test
Minutes after the guarantee question, Menin asked each company to commit under oath not to release a model that fails its own tests or a test by an outside reviewer the company did not choose. Each described its own review before release instead of answering yes or no. Menin said she would take the four answers as “sort of an equivocation.”
The commitment she asked for is at the center of a bill she is sponsoring. It would make it illegal to sell or use an AI model in New York City unless an outside reviewer has checked it and a person can shut it down. The reviewer would check, among other things, the model’s safety and whether the shut-down works. Fines would run up to $25,000 for each violation.
Menin’s bill was formally introduced three days later
Menin formally introduced the bill to the full Council on Oct. 8, three days after the hearing. It now sits with the Committee of the Whole, the committee made up of all 51 Council members that held the hearing. No vote has been scheduled.